Peer review stands as the primary quality control mechanism in scientific publishing, yet widespread misunderstanding surrounds what this process actually achieves. Journals send submitted manuscripts to independent experts who evaluate methodology, logic, and contribution before publication. This system filters research entering the scientific record, but its limitations matter as much as its strengths.
The process provides no stamp of absolute truth. Reviewers assess whether claims follow logically from presented evidence and whether methods appear sound, but they work with information authors choose to provide. A paper passing peer review means experts found no obvious flaws in the narrative presented, not that every statement within reflects reality.
The Mechanics of Editorial Gatekeeping
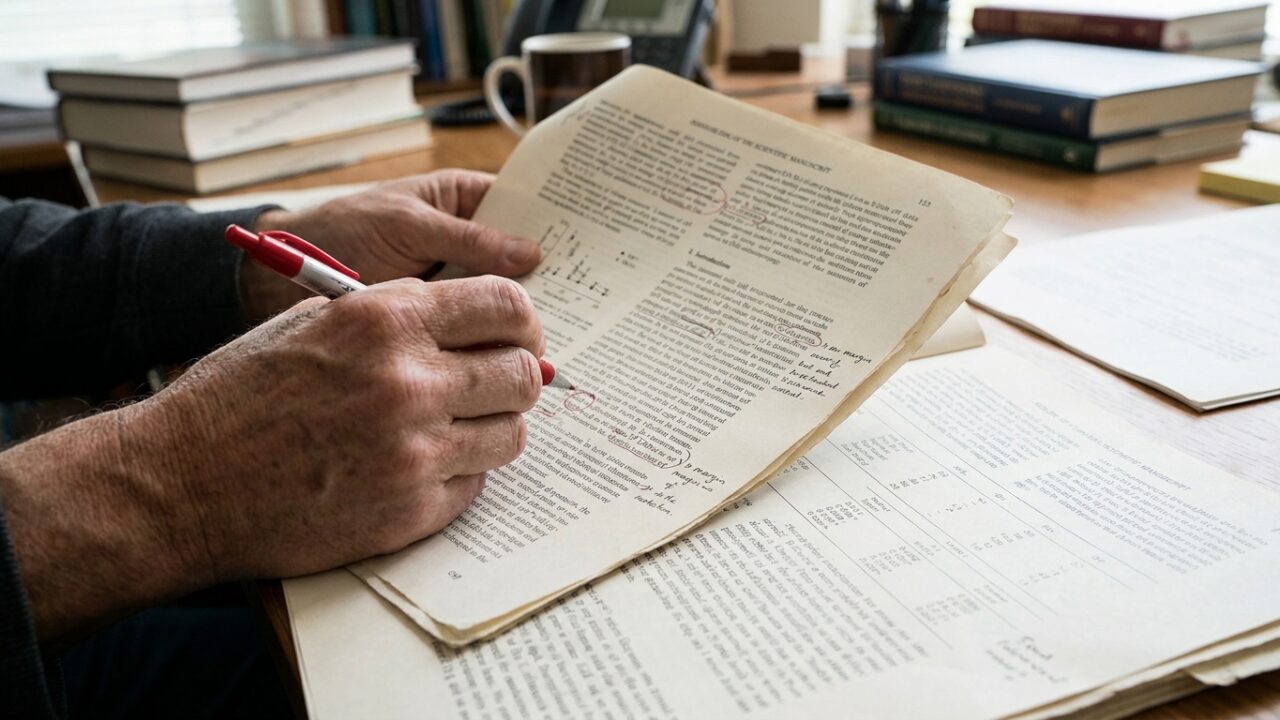
When researchers submit a manuscript, editors first determine whether the topic fits the journal’s scope and meets minimum standards. Papers that pass this initial screening go to typically two or three reviewers with relevant expertise. These reviewers receive the manuscript, sometimes anonymously, and provide written assessments addressing specific questions.
Reviewers evaluate whether the research question matters, whether the experimental design can answer that question, whether the statistical analysis suits the data, and whether conclusions overstep the evidence. They check if authors cite relevant prior work and if the writing communicates clearly. Based on these assessments, they recommend acceptance, revision, or rejection.
Editors synthesize reviewer comments and make final decisions. Authors receive feedback and typically must address criticisms point-by-point before publication. This back-and-forth can require multiple revision rounds spanning months or years.
What the System Actually Catches
Peer review effectively identifies methodological weaknesses that authors overlook. Reviewers spot inappropriate statistical tests, recognize confounding variables ignored in experimental design, and notice when sample sizes lack power to support claims. They catch logical leaps where conclusions exceed what data demonstrate.
The process also enforces field norms. Reviewers ensure authors acknowledge competing explanations, cite foundational work, and place findings within existing literature. They push for clearer writing when jargon obscures meaning or when crucial details go unexplained.
Peer review filters submissions that fall below disciplinary standards. It rejects papers with such severe flaws that publication would waste journal space and reader attention. This gatekeeping function prevents the scientific literature from drowning in low-quality noise.
The Boundaries of What Reviewers Can Verify
Reviewers cannot confirm that experiments actually occurred as described. They evaluate protocols based on written descriptions, but they do not observe laboratory work, examine raw data files, or verify that samples existed. Fabricated data presented in plausible tables and graphs will pass review if nothing raises suspicion.
The system assumes honesty. Reviewers check whether reported results could plausibly arise from stated methods, but detecting sophisticated fraud requires forensic analysis beyond the review process. Image manipulation, selective reporting of experiments, and invented patient records have all appeared in peer-reviewed journals because reviewers had no reason to question authenticity.
Reproducibility remains untested at the peer review stage. Reviewers assess whether methods contain sufficient detail for replication attempts, but they do not actually repeat experiments. A paper may describe procedures clearly yet report results that no other laboratory can obtain. The review process cannot distinguish reliably reproducible findings from statistical flukes or laboratory-specific conditions.
Reviewer Expertise and Blind Spots
The quality of peer review depends entirely on reviewer selection. Editors choose reviewers based on publication history and stated expertise, but matching specialists to interdisciplinary work proves difficult. A neuroscience paper using novel computational methods might go to neuroscientists who cannot evaluate the algorithms or to computer scientists unfamiliar with brain anatomy.
Reviewers volunteer their time without compensation, squeezing manuscript evaluation into already full schedules. They may spend a few hours on a paper representing years of work. Time pressure combined with limited access to raw data means reviewers sample rather than comprehensively examine submitted work.
Cognitive biases affect even expert reviewers. Findings that confirm existing theories receive gentler scrutiny than those challenging established views. Papers from prestigious institutions or famous researchers may benefit from halo effects. Novel methodologies that reviewers do not fully understand sometimes slip through because reviewers hesitate to reveal knowledge gaps.
The Anonymity Question
Many journals use single-blind review where reviewers know author identities but authors do not know reviewers. Some employ double-blind processes hiding both. Others use open review with all parties identified. Each approach carries tradeoffs between accountability, bias reduction, and frank criticism.
Double-blind review aims to prevent bias based on author reputation, gender, or institutional affiliation. However, research topics and writing styles often reveal authors in specialized fields. Single-blind review allows reviewers to consider an author’s track record while protecting reviewers from retaliation. Open review increases accountability but may discourage harsh but necessary criticism of powerful figures.
Post-Publication Reality Checks
The true test of scientific work comes after publication. Other researchers attempt to build on findings, replicate key experiments, or apply methods to new questions. This post-publication scrutiny often reveals problems peer review missed.
Replication attempts expose fragile findings that depended on specific unstated conditions. Meta-analyses combining multiple studies reveal whether initial positive results represented true effects or statistical noise. Critics examining published papers with more time than reviewers had discover errors in calculations, inappropriate statistical tests, or alternative explanations for results.
Some fields have experienced replication crises where large percentages of published findings fail to hold up under repeated testing. Psychology, cancer biology, and preclinical research have all confronted evidence that peer review allowed substantial amounts of unreliable work into the literature.
Working Within System Constraints
Understanding peer review’s limitations changes how scientific consumers should interpret published research. A peer-reviewed publication means the work met minimum standards and survived expert criticism, not that every claim within is correct. Confidence in findings should increase with independent replication, consistency across multiple studies, and plausibility given other established knowledge.
Researchers themselves bear responsibility for rigor that peer review cannot enforce. Transparent practices like sharing raw data, registering hypotheses before experiments, and publishing negative results address weaknesses in the peer review filter. These practices allow post-publication scrutiny to work more effectively.
Peer review functions as an initial quality screen, not a certification of truth. It catches obvious errors and strengthens methodology through critical feedback, but it cannot detect fraud, confirm reproducibility, or guarantee that published findings will stand the test of time. Scientific reliability emerges from the entire ecosystem of publication, replication, criticism, and synthesis rather than from any single checkpoint.